
Have you ever watched the market move hard while your exchange suddenly stops responding? That exact frustration hit many traders early on October 30 when Kraken experienced a sudden trading disruption lasting roughly one hour. Orders refused to go through. Connections dropped. Some users even found withdrawals temporarily blocked. Then, almost as quickly as it began, everything came back online. In a space where minutes can mean serious money, that kind of pause leaves a mark.
What Exactly Happened During The Kraken Trading Outage
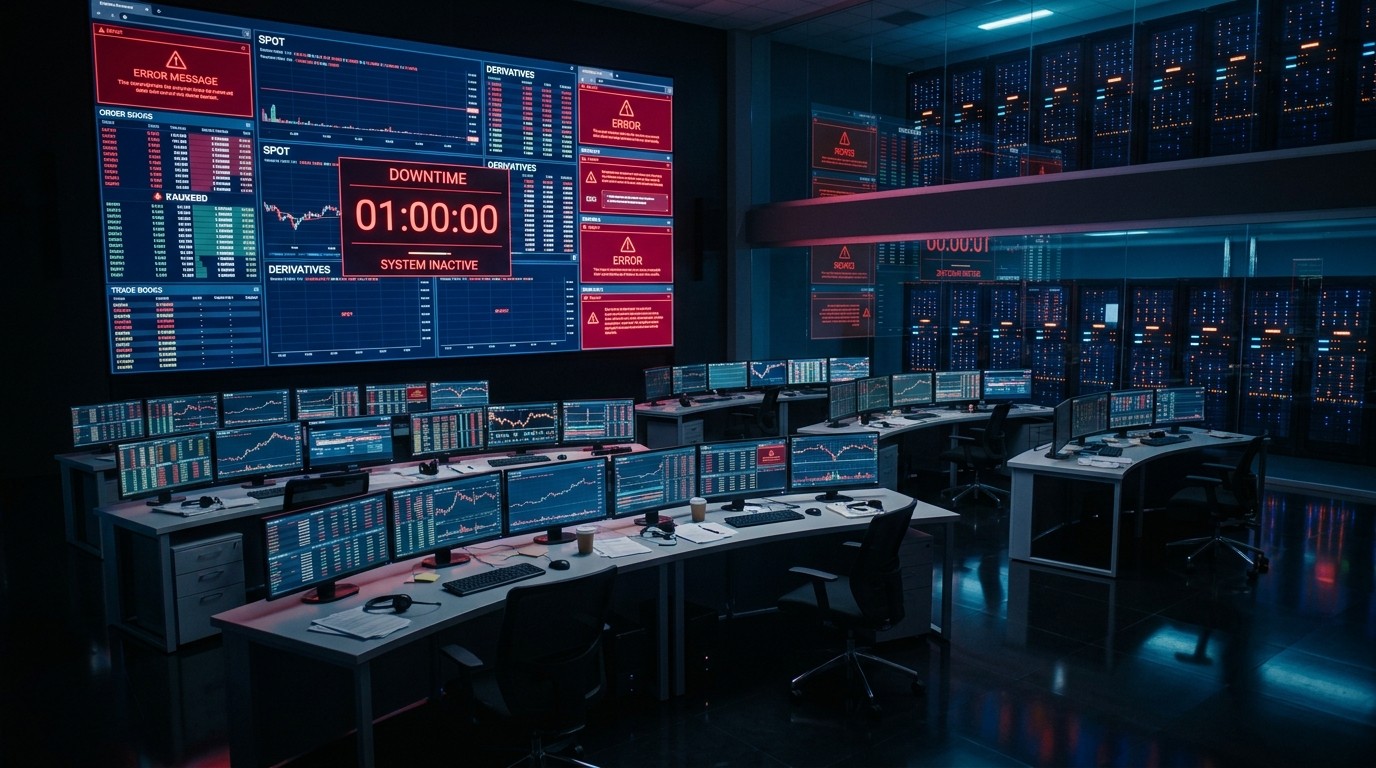
The problems started around 02:42 UTC. According to the exchange’s own status updates, connectivity issues and order placement failures began affecting both spot and derivatives markets at the same time. Website access became unreliable. Mobile apps struggled. API connections that many automated systems rely on, including REST, WebSocket, and FIX, also ran into trouble.
I’ve followed enough of these incidents over the years to know the pattern. First comes the quiet investigation notice. Then a short follow-up. Finally the “resolved” message. In this case the full cycle took about sixty minutes. By 03:42 UTC the exchange confirmed the incident was over. Still, for anyone trying to enter or exit a position during that window, those sixty minutes felt a lot longer.
Services That Took The Hit
The list of affected components was fairly broad. Regular web users and mobile app users both reported problems. Professional and algorithmic traders relying on API endpoints faced the same barriers. Even some cross-exchange transfer functions tied to the derivatives side experienced interruptions.
What stood out to me was the simultaneous impact on both spot and derivatives. Often an issue stays contained to one side of the platform. This time the disruption crossed both. That suggests the root problem sat somewhere deeper in the shared infrastructure rather than in a single product line.
Kraken never released a precise count of failed orders or locked accounts. From a trader’s perspective that absence of detail can feel frustrating. You want numbers. You want clarity. Instead you get a clean resolution notice and the expectation that business continues as usual.
Real User Experiences During The Downtime
While the official status page stayed relatively calm, social channels filled with immediate reactions. One trader described repeated error messages while trying to buy during a sharp market move. Support responded quickly, pointing people toward the live incident page and asking for patience.
Another user specifically asked about withdrawals. The reply confirmed the team was aware and working on it. A third trader claimed the platform appeared stuck in a post-only style mode for a stretch, meaning only certain limit orders that add liquidity could go through. Whether that was a deliberate protective setting or simply a side effect of the connectivity problems remains unclear. The exchange never confirmed a platform-wide post-only restriction.
These individual reports matter. They paint a picture of uneven impact. Some people could still view balances. Others could not submit any orders at all. A few found themselves locked out of moving funds just when they felt the need most. In volatile conditions that kind of uncertainty quickly turns into stress.
Timing And Recent Maintenance Context
Interestingly, the outage arrived the day after scheduled maintenance. On October 29 the exchange performed planned upgrades on its spot website and API services. Official notices warned of roughly fifteen minutes of unavailability starting at 08:01 UTC. Markets temporarily shifted into cancel-only and post-only modes while engineers verified systems. That work wrapped up by 08:17 UTC. Derivatives maintenance happened in the same window, and an earlier FIX API issue had already been cleared that morning.
Was the October 30 disruption connected to residual effects from the previous day’s work? The official incident report never made that link. Still, the proximity raises a fair question. Complex systems sometimes reveal stress only after traffic returns to normal levels. I’ve seen similar patterns on other platforms where a clean maintenance window is followed by an unexpected hiccup the next day.
Of course correlation does not equal causation. Without a detailed technical post-mortem we are left with educated guesses. The exchange may simply have encountered an independent infrastructure glitch. Or traffic spikes related to broader market events could have exposed a previously hidden bottleneck. Either way, the sequence of events is worth noting for anyone who tracks platform reliability closely.
Broader Market Atmosphere At The Time
The disruption did not occur in a vacuum. Cryptocurrency markets were already operating under elevated tension following a major security incident at another large exchange. Price action had grown more erratic. Liquidity conditions felt thinner in places. In that environment any additional friction on a major platform tends to amplify anxiety.
Some observers floated unconfirmed claims about substantial exposure to a decentralized lending protocol. Figures north of one hundred thirty million dollars circulated in certain circles. Those numbers remain speculative. No public evidence tied the alleged exposure directly to the connectivity problems. Still, the timing invited the speculation. When platforms experience technical issues during periods of market stress, theories multiply quickly.
Kraken has previously shared information about its DeFi-related products. Customer deposits into certain yield features have been directed toward third-party lending protocols through managed vault structures. Those arrangements involve independent risk oversight. Cumulative deposit figures often get mistaken for direct balance-sheet exposure. They are not the same thing. Understanding that distinction helps separate signal from noise when rumors start flying.
Why Short Outages Still Matter
Sixty minutes does not sound catastrophic on paper. In traditional markets an hour of downtime might pass with limited comment. Crypto moves differently. Liquidity can evaporate in minutes. Liquidation cascades develop fast. Traders running leveraged positions need the ability to adjust or close those positions without delay.
I have spoken with enough active participants over the years to recognize a common theme. Reliability is no longer a nice-to-have feature. It sits near the top of the checklist when people choose where to keep funds and execute strategies. A platform can offer tight spreads, deep books, and attractive fee schedules. If the matching engine or connectivity layer becomes unreliable at critical moments, those advantages lose value.
There is also a psychological layer. Once trust erodes even slightly, some traders begin keeping smaller balances on the platform or routing more activity elsewhere. That behavior compounds over time. Exchanges that maintain strong uptime records tend to attract and retain sophisticated flow. Those that experience repeated short interruptions risk gradual migration of that flow.
Practical Lessons For Active Traders
Incidents like this serve as useful stress tests for personal risk management. A few practical points stand out.
- Maintain accounts on more than one major platform so an outage on one does not freeze your entire ability to trade
- Keep a portion of dry powder in wallets you fully control rather than on any single exchange
- Monitor official status pages and support channels in real time during volatile sessions
- Understand which order types remain available under degraded conditions
- Review liquidation thresholds carefully when holding leveraged positions overnight or across uncertain periods
None of these steps eliminate risk. They simply reduce the chance that a single point of failure turns a manageable market move into a forced loss. In my own approach I treat exchange uptime as part of the overall risk budget. Position sizing already accounts for market volatility. It should also account for possible temporary inability to act.
How Exchanges Typically Handle These Events
Most established platforms follow a similar communication playbook. An initial investigation notice appears. Engineers dig into logs and system metrics. Intermediate updates keep the timeline visible. Once service restores, a final resolution message goes out. Sometimes a more detailed post-mortem arrives days later. Sometimes it does not.
Transparency levels vary. Some teams publish root-cause analysis that names specific components and mitigation steps. Others stay high-level. From a user perspective the more concrete information the better. Knowing whether the problem involved a database lock, a network routing issue, or a capacity limit helps set expectations for future resilience.
In this particular case the public record stayed relatively concise. The timeline is clear. The affected services are listed. The cause remains internal. That approach is common and legally cautious. It also leaves room for continued speculation among the community.
Looking At Platform Reliability Trends
Exchange outages are nothing new. Almost every major venue has experienced them at some point. What has changed is the speed at which information travels and the size of the capital now sitting on these platforms. A one-hour interruption today affects far more value and far more participants than a similar event five or six years ago.
Competition among platforms has also intensified. New venues continue to appear. Existing ones expand product offerings and geographic reach. In that environment operational excellence becomes a differentiator. Traders notice which platforms stay online during turbulent sessions and which ones struggle.
Perhaps the most interesting aspect is how quickly some platforms recover. Sixty minutes represents a relatively short window compared with multi-hour or multi-day events seen elsewhere in the past. Speed of recovery matters almost as much as prevention. The ability to diagnose, contain, and restore service under pressure speaks to the strength of the engineering and operations teams.
The Role Of Communication In Building Trust
Support responses during the outage were generally prompt. Users who reached out received acknowledgment and links to the live status page. That kind of rapid reply helps. Silence breeds frustration. Even a short message confirming awareness reduces the sense of isolation many traders feel when systems fail.
Still, there is room to improve across the industry. Real-time status pages that update automatically and offer clearer technical language would help. So would clearer guidance on what users should or should not attempt during degraded conditions. Simple instructions about whether to keep retrying orders or wait can prevent additional load on already stressed systems.
I have found that platforms which treat communication as a core reliability function tend to retain goodwill even after imperfect performance. Those that go quiet or provide only vague updates often face longer-lasting reputation damage.
What Traders Should Watch Next
In the days following any outage several signals are worth monitoring. Does the platform publish a more detailed explanation? Do additional smaller incidents appear in quick succession? How does order book depth and volume compare with pre-outage levels? Are support response times returning to normal?
These observations help separate one-off events from emerging patterns. A single short disruption can be noise. A cluster of issues over a short period suggests something deeper that still needs attention.
Market participants also tend to adjust behavior temporarily. Some reduce leverage. Others move a larger share of activity to secondary venues. Over time those adjustments either reverse or become permanent depending on subsequent performance.
Balancing Convenience And Control
Centralized exchanges remain the primary venue for most active trading. They offer speed, leverage, and deep liquidity that pure on-chain alternatives still struggle to match in many pairs. That convenience comes with a trade-off. Your ability to act depends on the platform remaining available.
Self-custody solves the availability problem for long-term holdings. It introduces its own challenges around transaction speed, gas costs, and the need to manage private keys carefully. Most experienced participants end up using a hybrid approach. Significant capital stays under personal control. Active trading capital sits on platforms chosen for reliability and depth.
The October 30 event simply underlines why that hybrid model makes sense. When the platform is healthy everything feels seamless. When it is not, the value of having options becomes obvious.
Final Thoughts On Platform Resilience
Technical interruptions will continue to occur. Software is complex. Networks are imperfect. Traffic patterns shift without warning. The goal is not perfection. The goal is rapid detection, clear communication, and fast recovery.
Kraken restored full trading within an hour. That timeline is respectable by industry standards. The lack of a detailed public root-cause analysis leaves some questions open, yet the core service returned. For most users the practical impact was temporary inconvenience rather than lasting damage.
Still, every incident offers a chance to refine personal processes. Review your backup venues. Check how much capital sits on any single platform. Make sure you understand the exact conditions under which you can and cannot act. Those small habits compound into stronger overall resilience.
Markets will keep moving whether any individual exchange is fully available or not. The traders who navigate those moments most effectively are usually the ones who planned for temporary friction ahead of time. An hour of downtime is a useful reminder that planning still matters.
In the end the episode passed. Trading resumed. Attention shifted back to price action and the next set of market catalysts. Yet the memory of those blocked orders and error messages lingers for anyone who lived through the window. Reliability remains one of the quiet foundations of trust in this space. Platforms that treat it as a continuous priority tend to keep that trust over the long run.
For now the practical takeaway is straightforward. Stay aware of status pages during volatile sessions. Diversify access points. Size positions with the understanding that temporary inability to trade is always a non-zero possibility. Those simple steps turn an unexpected outage from a potential crisis into a manageable annoyance.
Crypto markets reward preparation as much as they reward insight. The latest short disruption on a major platform is simply another data point in that ongoing lesson.