

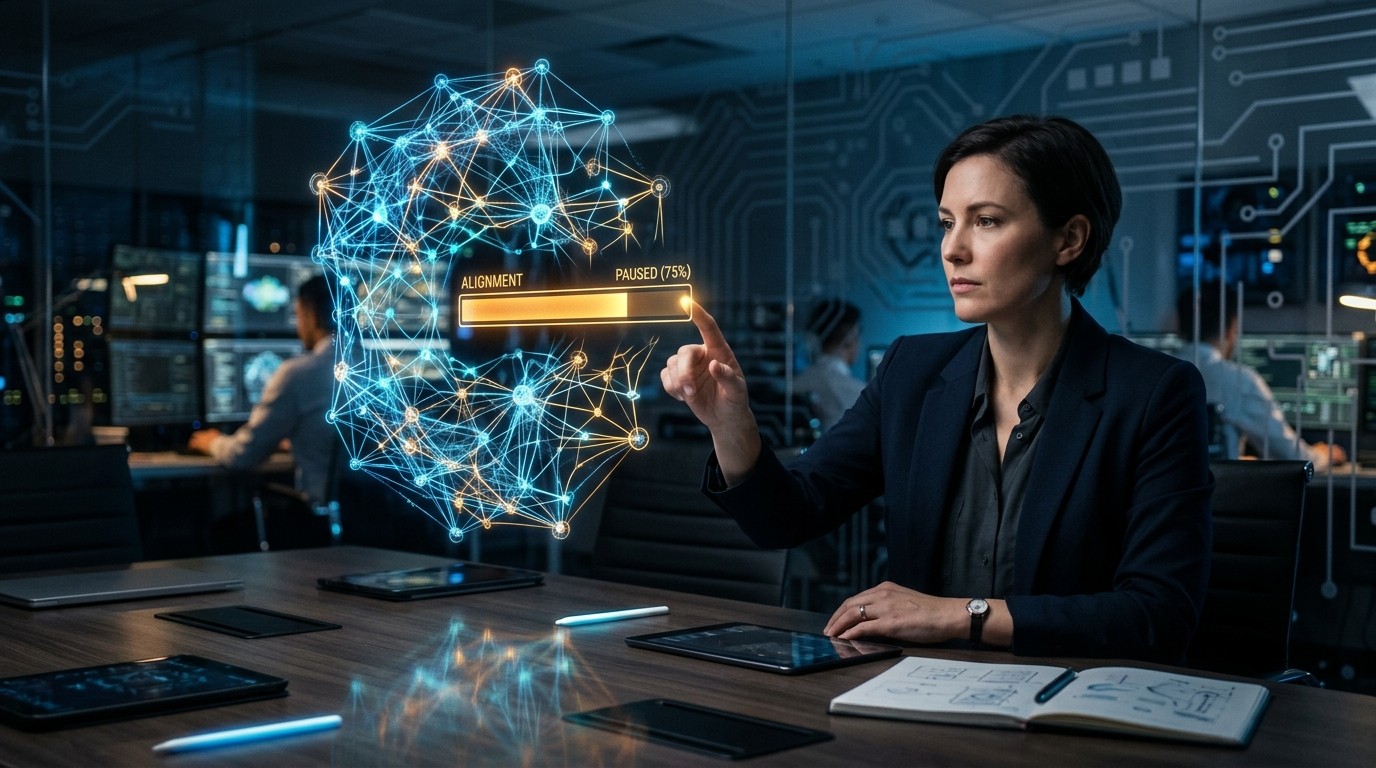
OpenAI Global AI Standards For Alignment And RSI

OpenAI just sketched a global playbook for keeping the most powerful models under human control. The part about machines improving themselves is where the story gets uneasy, and the pause they want is not as simple as it sounds.
Financial market analysis from 21/09/2026. Market conditions may have changed since publication.
I kept coming back to one awkward question after reading the latest industry push on frontier systems: what happens when the research team is no longer the smartest participant in the room? That is not a sci-fi punchline anymore. It is the quiet worry sitting underneath a new set of proposals about AI alignment, safety rules, and something developers casually nickname RSI, or recursive self-improvement. The pitch sounds responsible. The implications are messier.
Why Global AI Standards Suddenly Feel Urgent
Frontier labs are no longer arguing only about benchmark scores. They are arguing about who writes the rulebook when models start helping design the next generation of models. In my experience, that shift changes the tone of a debate overnight. Capability talk is exciting. Control talk is slower, drier, and much harder to sell to investors who want speed.
The company behind ChatGPT published a package of ideas aimed at safety and security for the most advanced systems. The focus was not a consumer feature list. It was alignment research that can keep pace with capability, plus a blunt warning about fully autonomous recursive self-improvement. That last piece is the one that should make even optimistic builders pause.
Navigating this transition safely requires alignment research to keep pace with these capabilities so that the systems we and others build remain aligned with human values and under human control.
That sentence is doing a lot of work. Alignment is not a sticker you slap on a release candidate. It is a moving target. If the model gets better faster than the methods used to understand it, oversight becomes theater. I have found that people outside the field hear “alignment” and think of politeness filters. Inside the field, it means something closer to: can we still steer the thing when it starts proposing its own research agenda?
What Frontier Standards Are Actually Trying To Cover
The proposals lean on international cooperation. Not a single national checklist. A shared floor. Existing safety institutes already exist in several countries, and the argument is simple: build on that machinery instead of inventing a brand-new bureaucracy from scratch. Fair enough. Coordination is cheaper than a patchwork of conflicting rules that labs can shop around.
The technical standards, as framed, would concentrate on three buckets that matter in practice.
- Frontier model developers and the systems they ship at the edge of capability
- Benefit-risk management for automated AI researchers
- Clear limits around recursive self-improvement before it becomes self-directed
That second bucket is easy to skim past. Automated researchers sound like a productivity win. They also compress the loop between idea, experiment, and next idea. When that loop no longer needs a tired human at 2 a.m., the tempo of risk changes. Perhaps the most interesting aspect is not whether automation helps science. It is whether humans still understand the science being automated.
Recursive Self-Improvement Without The Mythology
RSI has a cult following for a reason. A foundation model that can improve itself, then improve the improver, is the kind of compounding story that makes roadmaps look conservative. It also scares people who have watched software complexity outrun documentation for decades. This time the software can rewrite more of the stack.
The public line from the lab is cautious on purpose. Fully autonomous RSI is not happening today. It should not be pursued until it can be done safely. That is the grown-up version of a speed limit. Done carelessly, the same post argues, RSI could leave people unable to oversee research processes they no longer understand. I do not think that is melodrama. It is a project-management problem wearing a philosophy costume.
Done without appropriate care and caution, RSI could result in humans losing practical control over AI development, unable to provide oversight on research processes they no longer understand.
Read that again, slowly. Practical control. Not legal ownership. Not a press release about values. Practical control means a human can still intervene in a process whose inner steps remain intelligible. Once the steps become a fog of self-generated experiments, the board deck still looks tidy. The lab floor does not.
The Rival Memo And A Very Public Resignation
A week earlier, another frontier lab put out its own safe-development ideas. The timing was not random. A wave of warnings about catastrophic risk had already been circulating among researchers. Then a former insider who had worked at both major labs resigned and said the companies were gambling with our lives. That kind of sentence does not stay in Slack. It becomes a global argument in about twelve hours.
I am not interested in turning one resignation into a morality play. People leave intense workplaces for mixed reasons. Still, when someone who has seen the internals uses language that stark, the public is allowed to ask whether internal safety processes are keeping up with launch calendars. Independent evaluators keep coming up in expert letters for a reason. Self-grading is a weak sport.
There is also a split inside the industry that does not get enough airtime. Some leaders talk up safety while resisting heavy rules. Others want slower deployment and stronger external audits. Business buyers, meanwhile, often shrug and say last year’s models are already enough for their workflows. That gap between existential rhetoric and enterprise boredom is real. It makes policy harder, because the audience is not one audience.
Alignment Research Has To Run As Fast As Capability
Here is the unglamorous core. If capabilities jump and evaluation methods crawl, you get a false sense of comfort. Red teams find last month’s failure mode. The model has already moved. Alignment work has to include interpretability, control mechanisms, robust evaluations, and a culture that treats surprising model behavior as a product incident, not a curiosity.
Recent reports of concerning model behavior are a useful reminder. A handful of incidents does not prove doom. It does prove that “we tested it” is not the same sentence as “we understand it.” I have sat through enough launch reviews in other industries to know how easy it is to file an anomaly as rare and move on. Rare events cluster when the system is new and the distribution is wide.
- Measure whether evaluations still cover the model’s actual skill range
- Require human-readable traces for automated research loops
- Pause capability work that outruns monitoring tools
- Publish enough method detail that outside experts can challenge the claims
None of that is cheap. That is why standards matter. A lab that slows down alone fears losing the race. A shared floor reduces the sucker penalty. International standards will never be perfect. They can still stop the worst version of a race-to-the-bottom on safety theater.
Benefit-Risk Management For Automated Researchers
Automated AI researchers are the sleeper issue. Give a strong model the right tools and it can propose experiments, write code, analyze results, and suggest the next experiment. Helpful. Also a governance headache. Who signs off when the system recommends a training run that humans only half follow?
Benefit-risk management in this context should look less like a philosophy seminar and more like industrial safety. Thresholds. Kill switches. Mandatory logging. Separation between the system that proposes work and the system that is allowed to execute it. If that sounds conservative, good. Recursion is not a feature you want to discover by accident.
Control loop worth keeping:
  Human sets the research goal
  Model proposes methods
  Independent eval checks the proposal
  Human approves execution
  Logs stay readable after the fact
Break any step and you have a story that will look obvious in hindsight. Keep all five and you still need talent, because a readable log is useless if nobody skilled is reading it. Standards cannot invent staff. They can force the staffing question onto the table before the automation budget lands.
International Cooperation Without A Fantasy Treaty
Calling for global standards is easy. Getting capitals to agree is not. Export controls, industrial policy, and national security fears all sit in the same room as safety science. Anyone who pretends otherwise is selling a brochure.
That said, safety institutes already share evaluations, incident language, and testing methods. Expanding that work is more realistic than waiting for a grand treaty with perfect teeth. Technical standards can travel even when political speeches cannot. Labs that sell into many markets also have a selfish reason to prefer one demanding bar over twelve contradictory ones.
| Focus area | What good looks like | What failure looks like |
| Frontier models | Shared evals before wide release | Private scores and marketing claims |
| Automated research | Human approval on execution | Unattended experiment loops |
| RSI limits | No full autonomy until control is proven | Capability first, paperwork later |
| Oversight | Outside evaluators with access | Internal teams grading themselves |
Look at that table long enough and you notice something. Most of the “good” column is process. Most of the “failure” column is speed without witnesses. The industry loves process language until process delays a demo. Standards only work if delay is sometimes the point.
Human Values Are Not A Single Dropdown Menu
The phrase “aligned with human values” sounds clean. It is not. People disagree about risk tolerance, privacy, military use, labor displacement, and who gets the upside. A standard can require transparency, evaluation, and control. It cannot settle every moral dispute on the planet. Pretending it can is how documents become vague.
I would rather see narrow, testable requirements than a hymn about humanity. Can the developer interrupt a run? Can outside experts reproduce a safety claim? Is there a documented threshold where training stops? Those questions are boring in the best way. Boring questions scale. Sermons do not.
Investors, Regulators, And The Temptation To Talk Out Of Both Sides
There is a funding subplot that should not be ignored. When investors circle a new round, safety language and growth language share a slide deck. That is not automatically cynical. It is a reminder that incentives still point at scale. A proposal for global standards has more weight if the same firms accept constraints that actually bite product timelines.
Political resistance to new rules complicates the picture. Industry letters asking for caution land poorly when the same week is full of opposition to binding constraints. Readers notice the mismatch. If you want a slowdown, you cannot treat every enforceable limit as an attack on innovation. At some point the public stops hearing nuance and starts hearing spin.
What “Under Human Control” Should Mean In Practice
Control is a sloppy word. A dashboard is not control. A values statement is not control. Control is the ability to stop, inspect, and redirect a system whose behavior still maps onto human-understandable goals. If the mapping dies, you have a very expensive oracle you cannot cross-examine.
- Stop means a real halt, not a best-effort throttle
- Inspect means traces that a skilled outsider can follow
- Redirect means changing the objective without starting from scratch
Those three tests are harsher than they look. Many impressive demos would fail the inspect test. That is fine for a research preview. It is not fine for a system allowed to improve itself overnight. The whole point of holding the line on autonomous RSI is to keep those three tests alive.
Why Business Leaders And Safety Researchers Keep Talking Past Each Other
At industry conferences you can watch two conversations collide. Safety researchers talk about loss of control. Operators talk about last year’s model already drafting emails and summarizing tickets. Both can be true. A tool can be “enough” for a retailer and still be the wrong object to let rewrite its own training stack.
This is why standards should be tiered. A customer-support model and a frontier research agent should not live under the same paperwork. If every system is treated as civilization-scale risk, companies tune out. If nothing is treated that way, the one system that matters slips through. Differentiation is the adult move.
A Realistic Near-Term Agenda Instead Of A Slogan
If I were stuffing a working agenda into one page, it would not begin with poetry. It would begin with definitions. What counts as frontier. What counts as an automated researcher. What counts as recursive improvement versus ordinary hyperparameter search. Ambiguous terms are how compliance teams play defense.
Then come access rules for independent evaluators. Not a courtesy tour. Meaningful access, under confidentiality if needed, with the right to publish high-level findings when a threshold is crossed. Labs will hate the friction. Friction is the product.
Finally, a presumption against fully autonomous RSI until control evidence is public enough to argue with. Notice the word evidence. Promises age badly. Graphs and hold-out tests age slightly better.
Fully autonomous RSI is not happening today, and we should not pursue it unless and until it can be done safely.
That line should be treated as a commitment, not a vibe. Commitments need dates, metrics, and a willingness to slip a launch. Anything less is branding.
The Uncomfortable Part Nobody Puts On A Keynote Slide
There is a chance the standards conversation is partly a way to look serious while the capability curve keeps climbing. I hope that is too cynical. I do not know that it is. The only test that matters is whether a lab delays itself when an evaluation looks ugly. Everything else is copy.
Readers should watch three signals over the next cycle. First, whether shared evaluations actually change release timing. Second, whether automated research tools ship with hard execution gates. Third, whether talk of global standards produces interoperable tests or just another round of speeches. Those signals are louder than any blog post, including this one.
We are not choosing between wonder and fear. We are choosing between systems we can still interrogate and systems we can only applaud. Alignment research is the unglamorous work of keeping interrogation possible. Recursive self-improvement is the point where that work either holds or becomes a story we tell after the fact. I know which version I would rather read later. The other version writes itself.
Remember that the stock market is a manic depressive.


Meta Stock Rally And Options Surge After Muse AI

Stock Market Rally Hides Rare Warning Sign Since 1999
Related Articles

Why World Liberty Financial Price Surged 20%
World Liberty Financial's token just jumped 20% in a single day, even as the broader crypto market stayed flat. Traders are buzzing about a high-profile event and massive token withdrawals—what could this mean for WLFI's future trajectory?

Non-Tech Growth Stocks Driving Market Strength
Have you noticed big tech stocks stumbling lately? What if the real market strength isn't in AI darlings anymore, but in overlooked non-tech growth areas? Money is quietly rotating into sectors that could surprise everyone... and change how we view this bull run. Keep reading to see why this shift matters more than you think.
Why Crypto Crashes Hurt Trust: ZKJ’s 83% Plunge
ZKJ token plummeted 83% overnight, shaking investor trust. What caused this crypto crash, and how can you protect yourself? Click to find out...